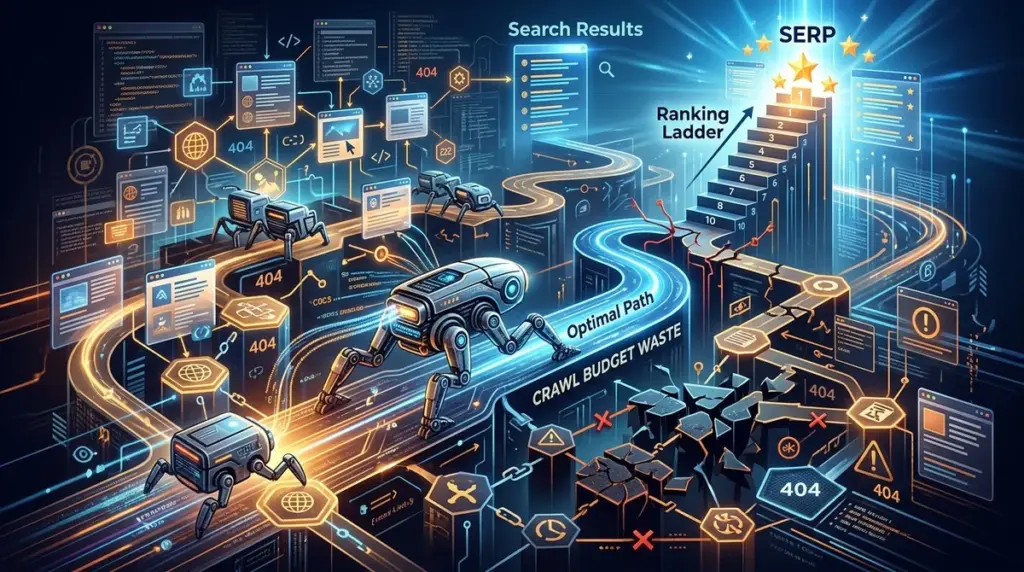
For enterprise-level sites and publishers managing thousands of URLs, crawl budget is not a theoretical SEO concept; it is a resource allocation constraint that directly dictates how quickly new content ranks and how accurately existing rankings reflect site updates. If Googlebot spends its finite time processing low-value parameters, session IDs, or infinite redirect loops, your high-priority commercial pages remain unvisited. This delay in discovery leads to stagnant rankings, where optimizations made weeks ago fail to register in the Search Engine Results Pages (SERPs) because the crawler simply hasn't returned to see the changes.
The Mechanics of Crawl Rate Limit and Crawl Demand
Google defines crawl budget as the combination of "crawl rate limit" and "crawl demand." Understanding the distinction is vital for troubleshooting ranking drops. The crawl rate limit is a technical ceiling designed to prevent Googlebot from crashing your server. If your hosting environment is sluggish or returns frequent 5xx errors, Google throttles its activity to protect user experience. Conversely, crawl demand is driven by the perceived importance of your URLs. Popular pages and those with high update frequency earn more "demand."
When these two factors are misaligned, ranking volatility occurs. A site with high demand but a low rate limit will suffer from "crawl lag," where the index becomes an outdated snapshot of the site. For an e-commerce platform, this might mean out-of-stock products continue to rank while new arrivals remain invisible to searchers.
Identifying High-Waste Crawl Paths
To improve ranking stability, you must eliminate "crawl waste." This refers to any URL that Googlebot reaches but which offers no unique value to the index. Common culprits include:
- Faceted Navigation: E-commerce filters (size, color, price range) can generate millions of unique URLs that provide duplicate content. Without proper canonicalization or robots.txt disallows, these eat the majority of your budget.
- Session IDs and Tracking Parameters: Unique strings appended to URLs for analytics purposes create infinite loops of "new" content that Googlebot feels compelled to explore.
- Soft 404s: Pages that appear broken to users but return a 200 OK status code. Googlebot continues to crawl these "dead" pages, wasting resources that should be spent on live content.
- On-Site Duplication: Printer-friendly versions of pages or mobile-specific URLs that aren't correctly mapped via alternate tags.
Warning: Frequent 503 (Service Unavailable) or 504 (Gateway Timeout) errors are the fastest way to trigger a permanent reduction in your crawl rate limit. Google interprets these as a sign that your server cannot handle the current crawl intensity, and it may take weeks of stable performance to regain previous crawl levels.
How Crawl Latency Directly Suppresses Rankings
Rankings are not static; they are the result of a continuous re-evaluation of content quality and relevance. If your crawl budget is exhausted on junk URLs, the "time-to-index" for new content increases. For news publishers or fast-moving retail sites, a 48-hour delay in indexing can mean the difference between capturing a trend and missing the traffic window entirely.
Furthermore, crawl issues impact the "freshness" signal. Google rewards sites that update content regularly with better visibility for competitive terms. If the crawler is stuck in a redirect chain or bogged down by slow-loading scripts, it cannot verify that you have updated a page with more relevant information. Consequently, your competitors—who may have more efficient site architectures—will leapfrog you in the SERPs simply because their updates are processed faster.
The Role of Internal Link Architecture in Budget Distribution
Googlebot uses internal links as a roadmap. A shallow site architecture, where every important page is within three clicks of the homepage, ensures that the crawl budget is distributed toward your most valuable assets. Conversely, deep "orphan" pages or content buried under complex pagination are rarely crawled. If your high-margin product pages are hidden behind several layers of navigation, they will receive a lower crawl frequency, leading to lower perceived authority and diminished rankings.
Best for: Agencies managing large-scale migrations or site mergers. Auditing the internal link flow ensures that the "link juice" and the crawler's attention are focused on the new URL structure immediately, preventing a post-migration ranking collapse.
Strategic Use of Robots.txt and Nofollow
Directing Googlebot is as important as attracting it. The robots.txt file is your primary tool for "pruning" the crawl path. By disallowing access to administrative folders, internal search result pages, and specific URL parameters, you force the crawler to focus on the pages that actually drive revenue. While the rel="nofollow" attribute on individual links used to be a hard directive, it is now a hint. However, it remains a useful signal for preventing the discovery of low-value internal paths that don't need to be indexed.
Optimizing for Crawl Efficiency and Ranking Recovery
To turn crawl budget into a competitive advantage, focus on the technical health of your site. This is not about "tricking" the algorithm, but about making it as easy as possible for Google to find your best work. When the crawler encounters a fast, logical, and error-free site, it rewards that site with higher crawl frequency, which correlates strongly with ranking stability and growth.
Actionable Checklist for Crawl Optimization:
- Monitor the "Crawl Stats" report in Google Search Console to identify spikes in 404 or 5xx errors.
- Consolidate redirect chains; every "hop" in a 301 redirect consumes more of your budget and adds latency.
- Use the
Last-Modifiedheader to tell Googlebot exactly which pages have changed since its last visit. - Prune thin content that serves no user intent, reducing the total number of URLs the bot needs to process.
Frequently Asked Questions
Does every website need to worry about crawl budget?
No. Small sites with fewer than a few thousand pages generally do not face crawl budget constraints. However, if you have a massive site with millions of URLs or a site that generates pages dynamically, crawl budget becomes a critical ranking factor.
How do I know if my crawl budget is being wasted?
Check your server logs or the Search Console Crawl Stats report. If you see Googlebot spending a significant percentage of its time on URLs with parameters (like ?sort=price) or pages you have marked as 'noindex,' you have a crawl waste problem.
Can improving site speed increase my crawl budget?
Yes. A faster server response time allows Googlebot to request more pages in the same amount of time without hitting the crawl rate limit. Improving your Time to First Byte (TTFB) is one of the most effective ways to increase crawl capacity.
Do redirects consume crawl budget?
Every URL Googlebot hits counts toward your budget. A single redirect is manageable, but chains of three or more redirects significantly slow down the crawler and may lead it to abandon the path before reaching the destination page.